

We all have too many papers to read; in the past I have just dumped a bunch of related papers together with some light summary, to say why they’re interesting. This paper roundup is on evaluation and benchmarking, which has been a theme for me lately.
Benchmarking robotics is hard; collecting robotics datasets you can actually use is hard. This blog post is a short overview of a few datasets that might be of interest, both lesser-known ones that struck me as interesting and a few large and well-known ones for context.
You can also use this blog post to scroll through and see what the datasets people are talking about in a RoboPapers episode, actually look like.
If you like reading thoughts on robotics, please consider subscribing. Usually I write more in-depth summaries; this particular blog post is much more minimal and “stream of consciousness” than usual.
Datasets
Open X Embodiment
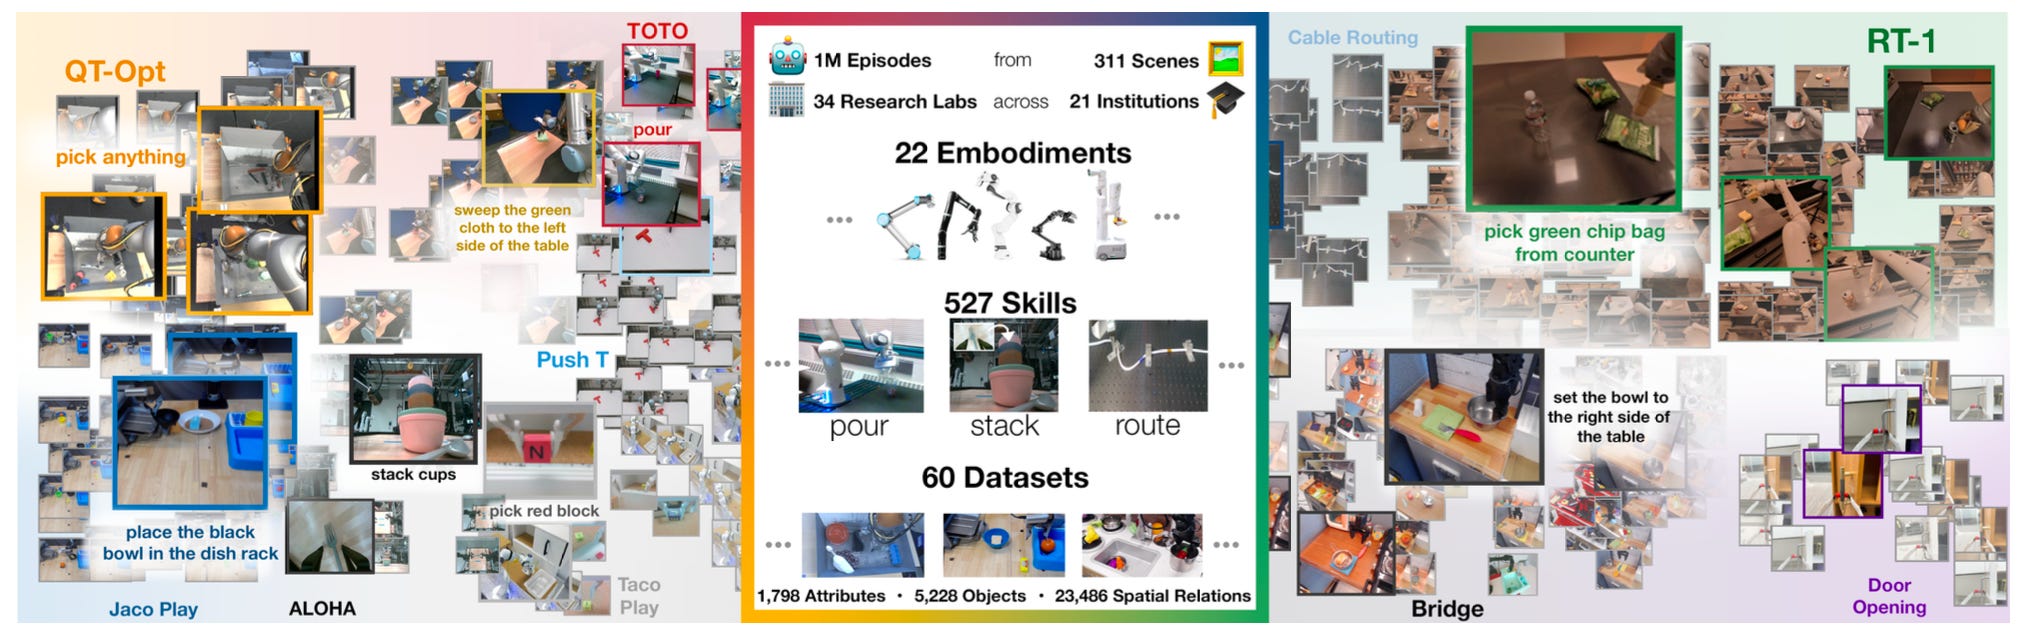
An absolutely huge dataset of robotics data. At the time of initial publishing, it had more than 500 skills and 150,000 tasks included, with a wide variety of robot embodiments. It won the ICRA 2024 best paper, and has about half a million authors. Find it here.
DROID
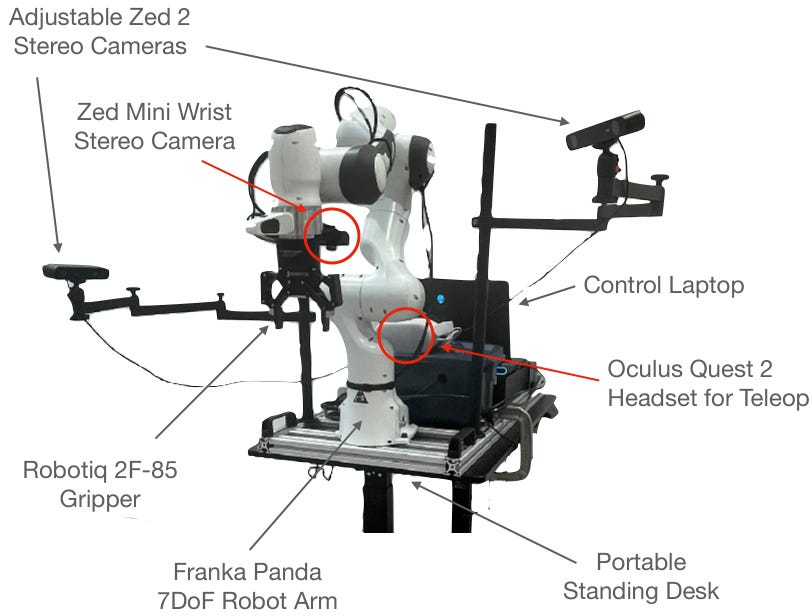
An important subset of Open X Embodiment, and a dataset that’s still heavily used today. Partly because the hardware setup (above) was duplicated across so many universities. Contains a mix of office, kitchen, and home environments, with a Franka Panda arm and a zed camera on the wrist, plus a number of third-person views.
Check out the website for more.
Build: 10k Hours of Egocentric Data
The Build team has released 10,000 hours of video data. 192,900 monocular wide-angle egocentric video clips, collected by human workers in a variety of different environments.
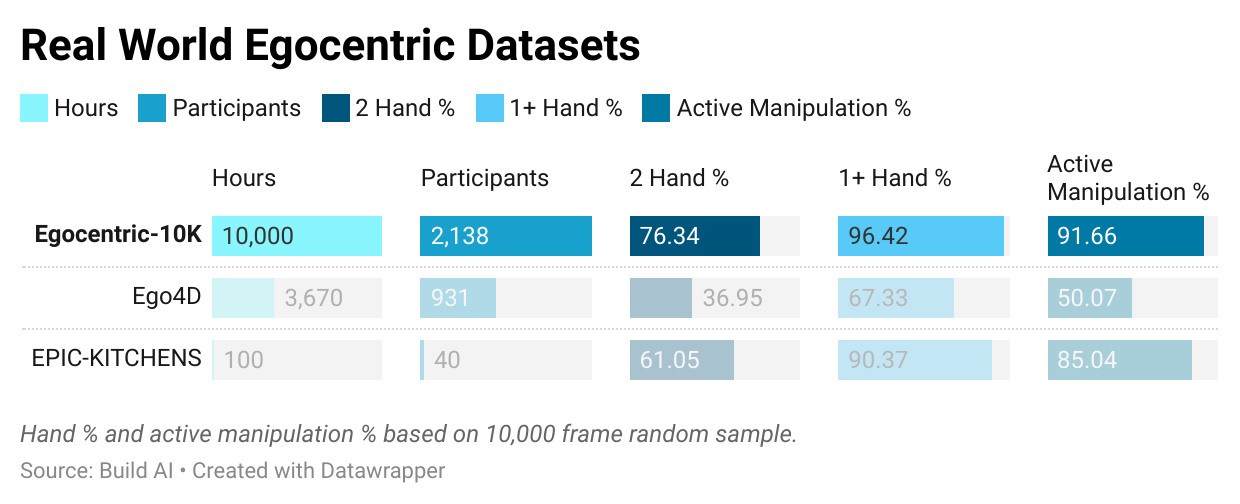
You can find the data here on HuggingFace. And look at Eddy Xu’s X thread.
OpenEgo: 1107 Hours of Egocentric Data
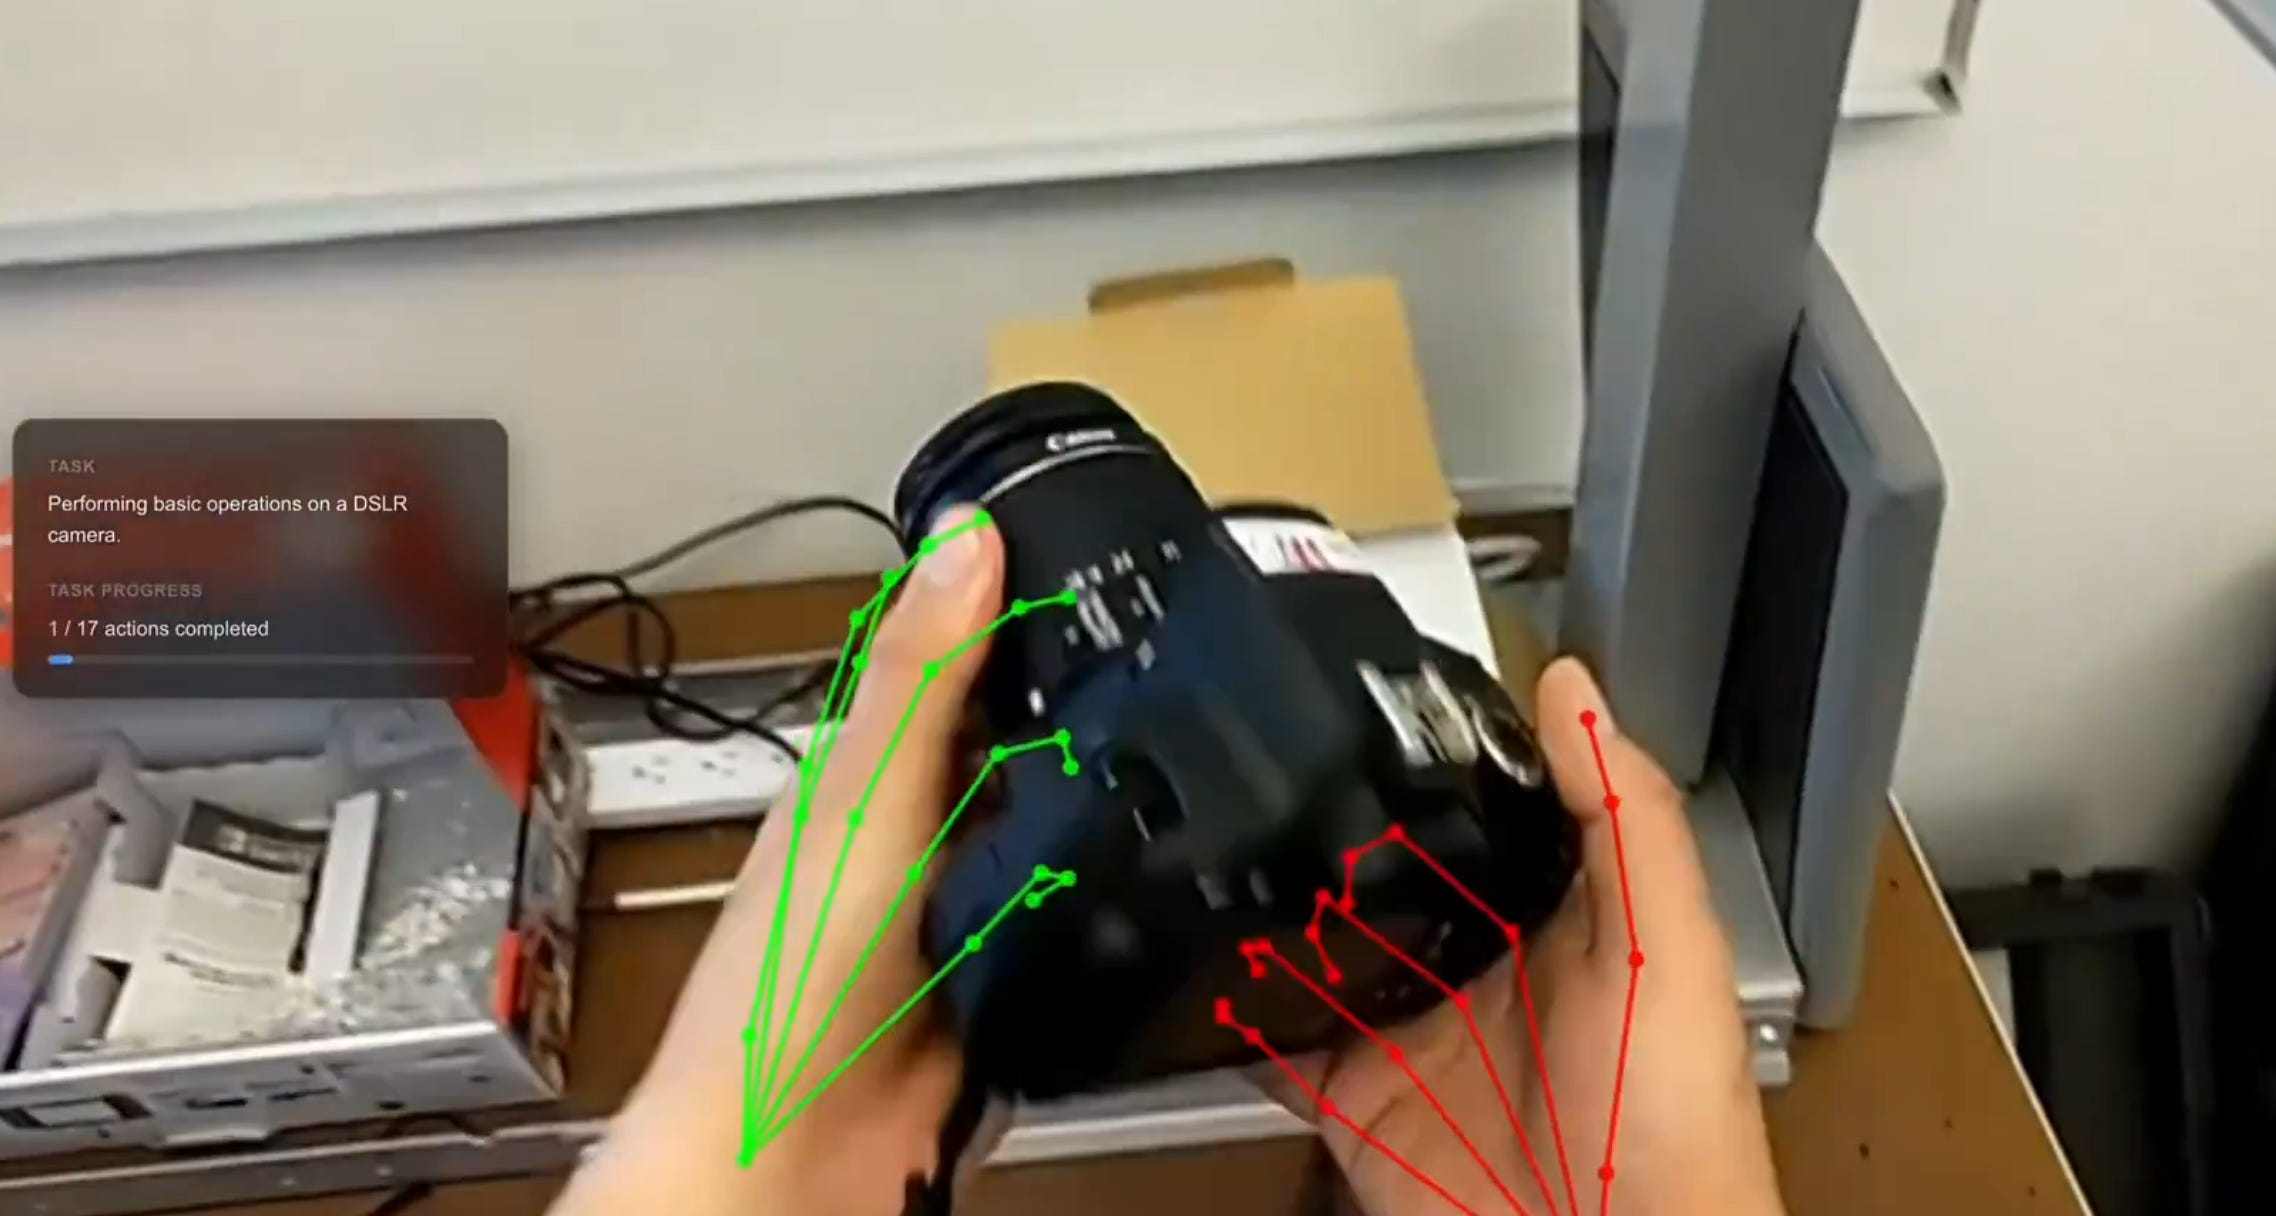
600+ environments with 120 million frames. Task, language, and 3D hand pose annotations. Often these datasets do not have annotations, so this part is potentially really valuable.
Check out the original X thread from Ahad Jawaid. Github site for OpenEgo.
ShareRobot: Task Planning
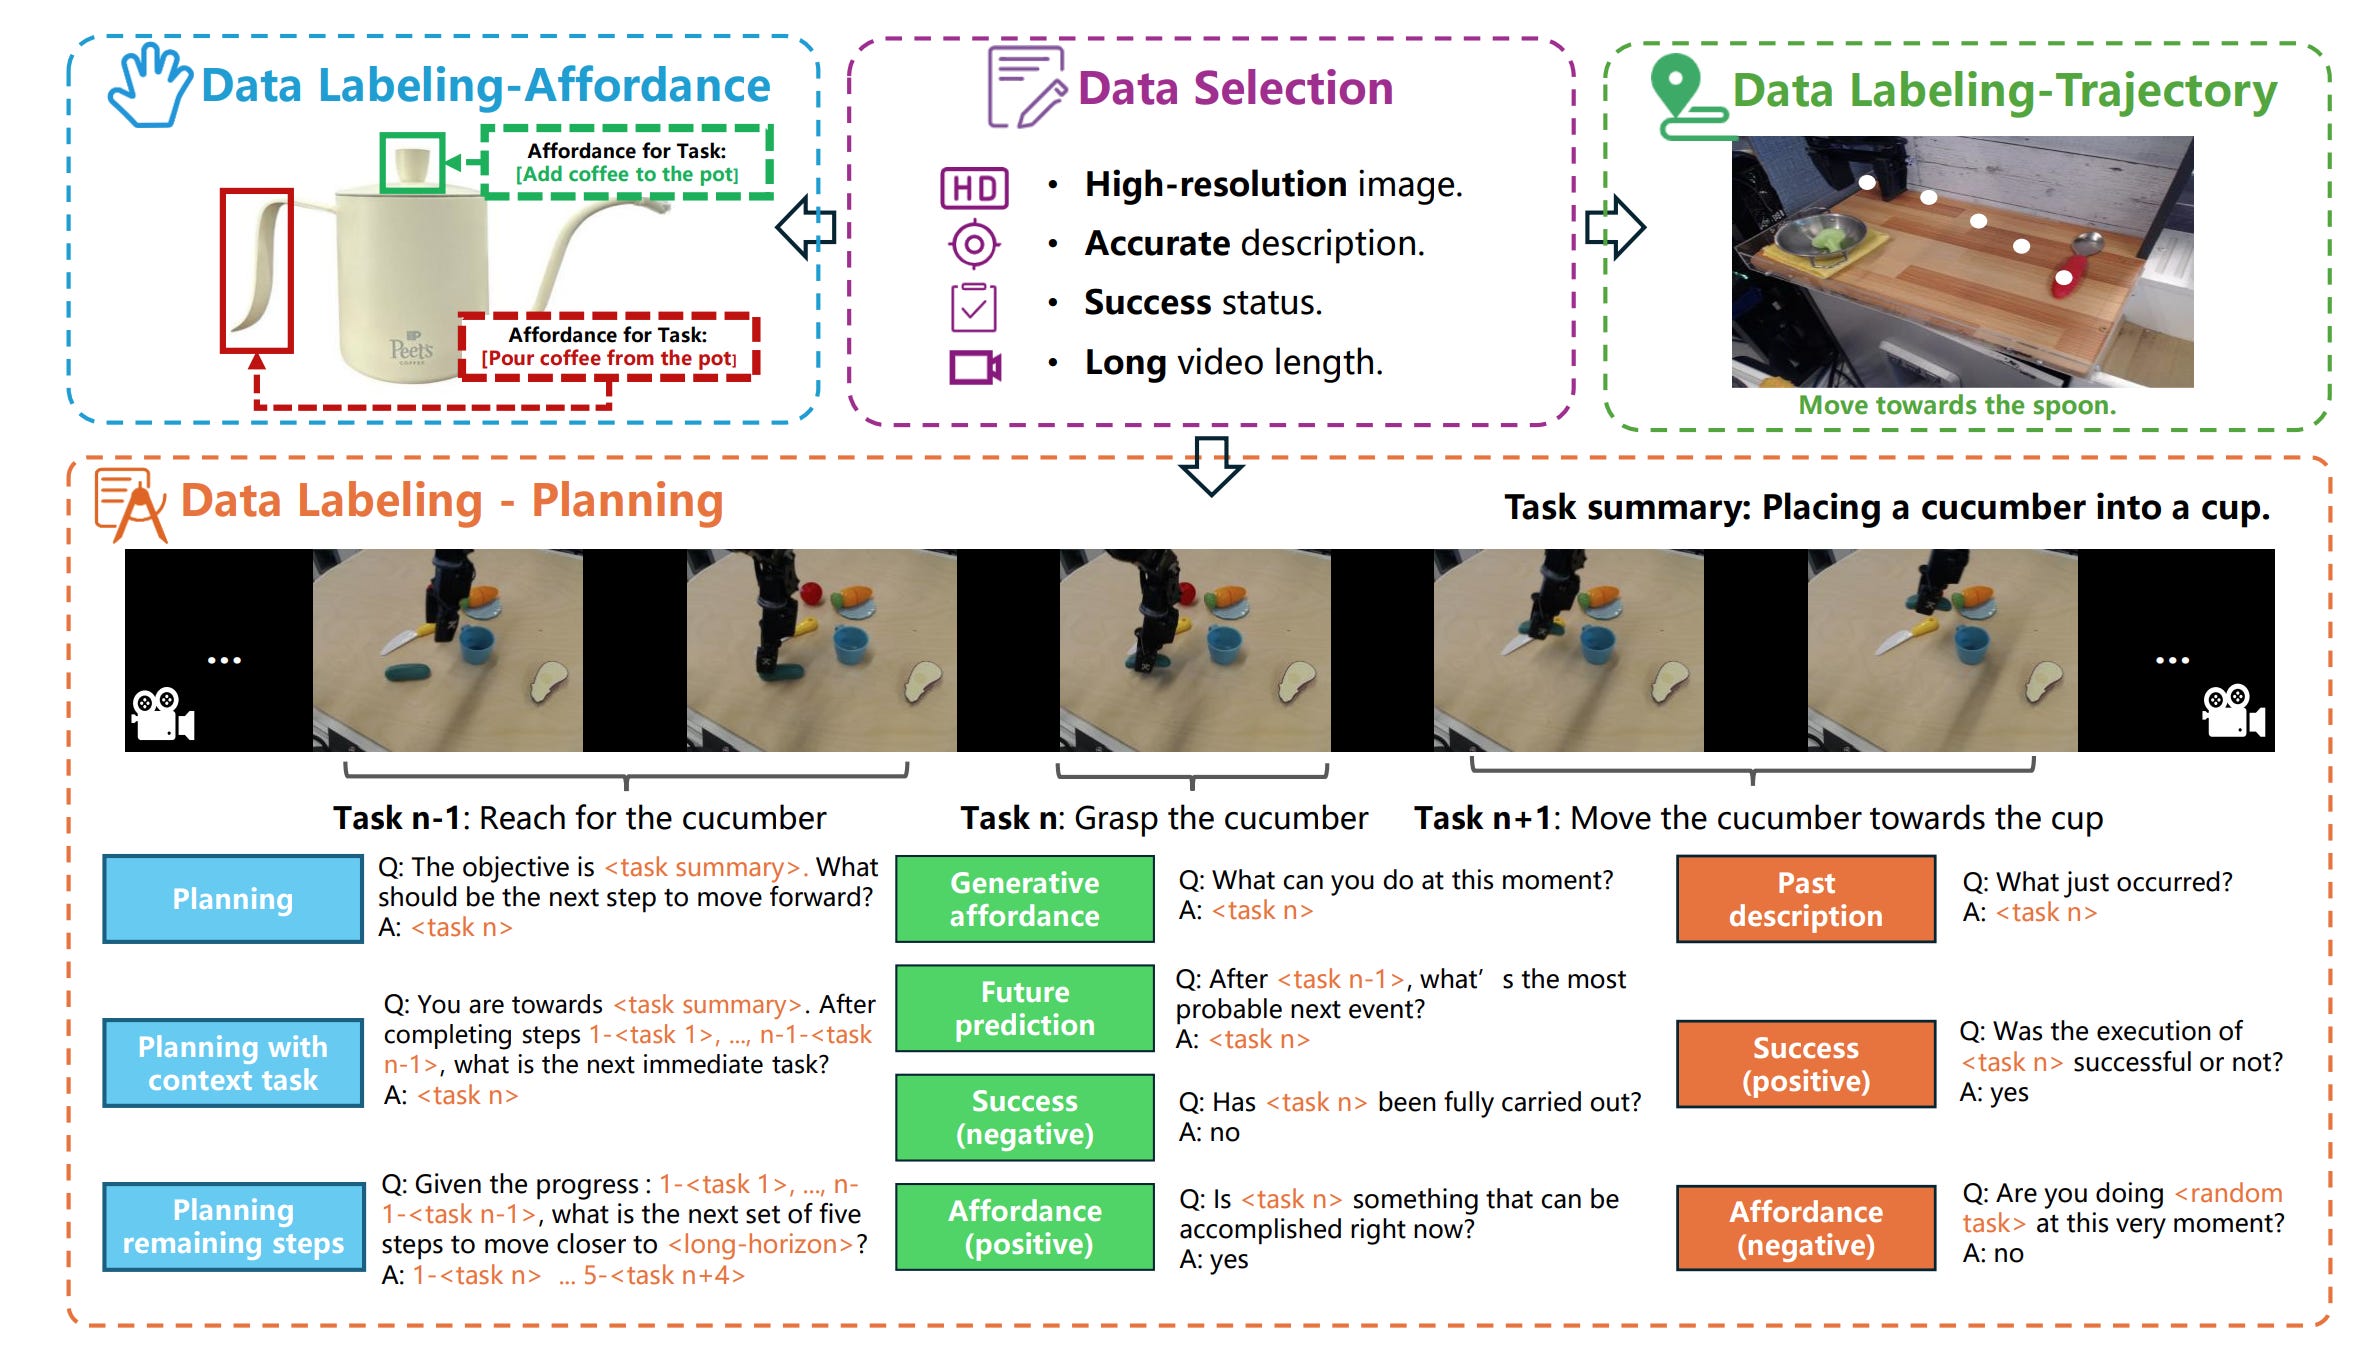
A task planning dataset, with complex multi-step tasks and question answering. You can find it on HuggingFace here.
HUMOTO: Human Object Interactions
A large interesting dataset of human-object interactions. Not sure how useful it is, but given how much object interaction in whole-body robot control has accelerated recently, this seems worth a look. You can check it out here.
Benchmarks
Libero
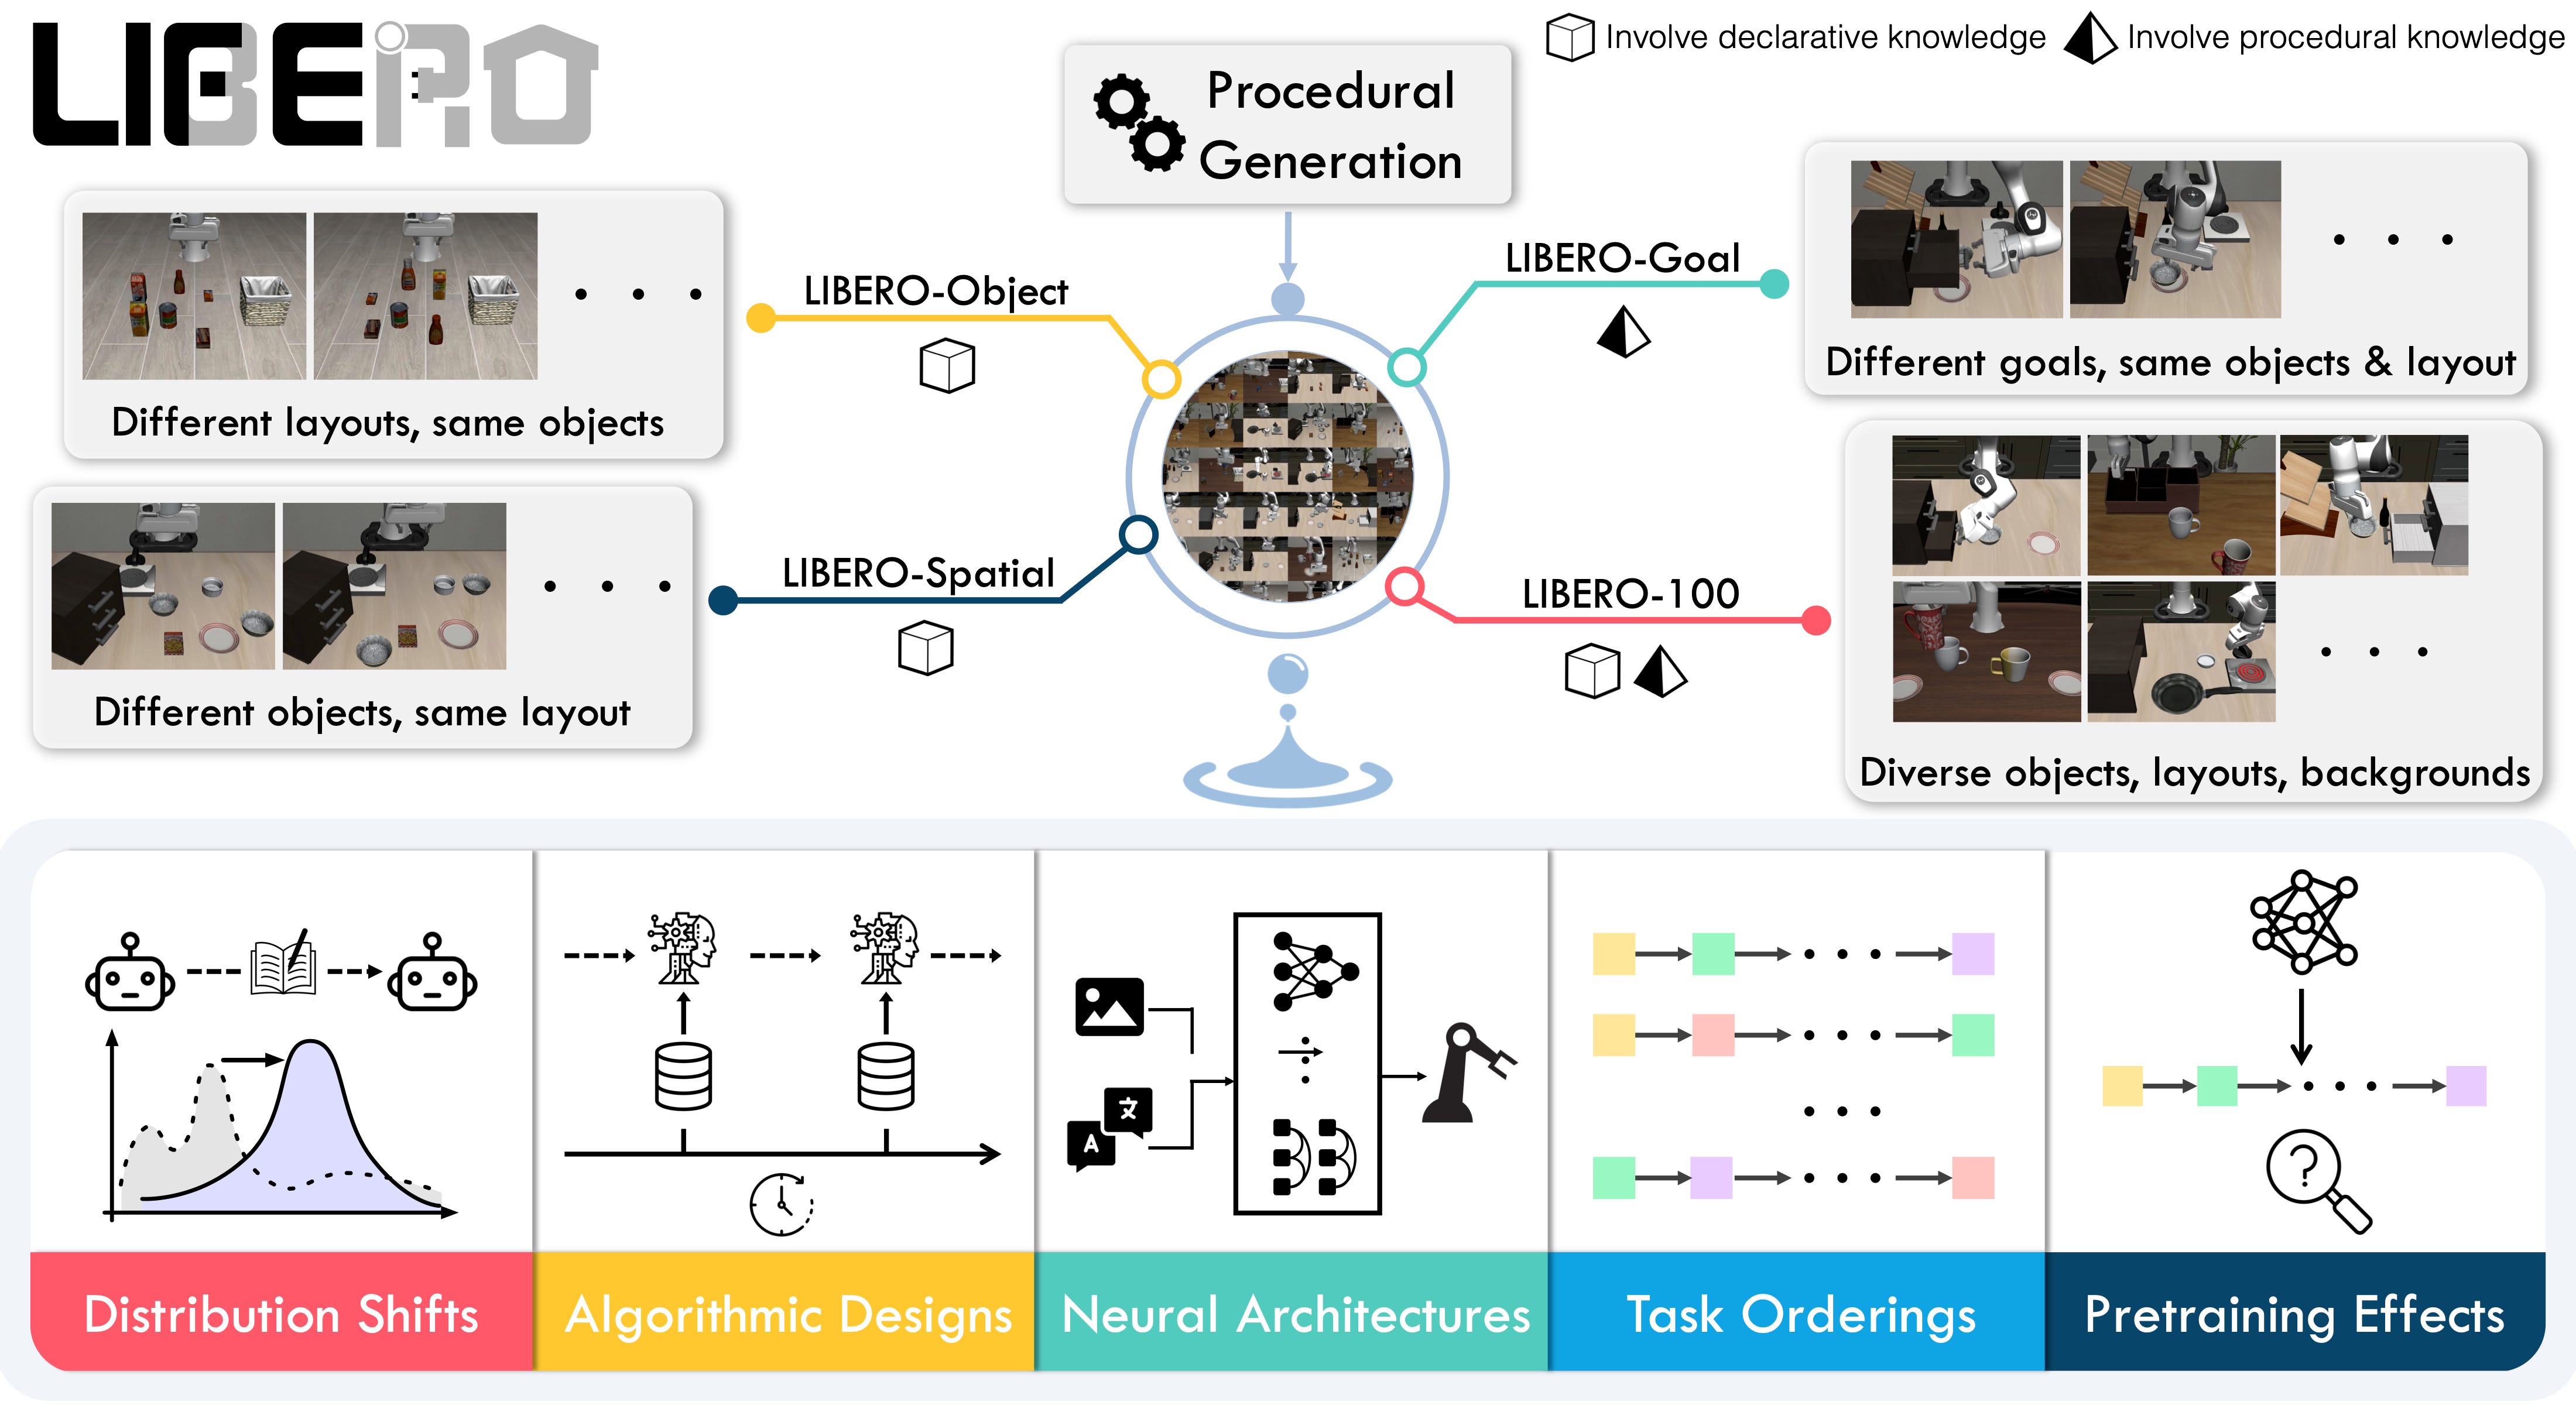
You probably know this one; it’s one of the biggest.
With 130 tasks spread out across 4 task suites, it has a lot of variety, and has been used in a ton of research papers so far. The code is also open source.
Contains datasets with RGB information from wrist cameras, proprioception data, language, and PDDL scene descriptions here. These are all high-quality human teleop data, making this benchmark highly suited for learning-from-demonstration research.
CALVIN
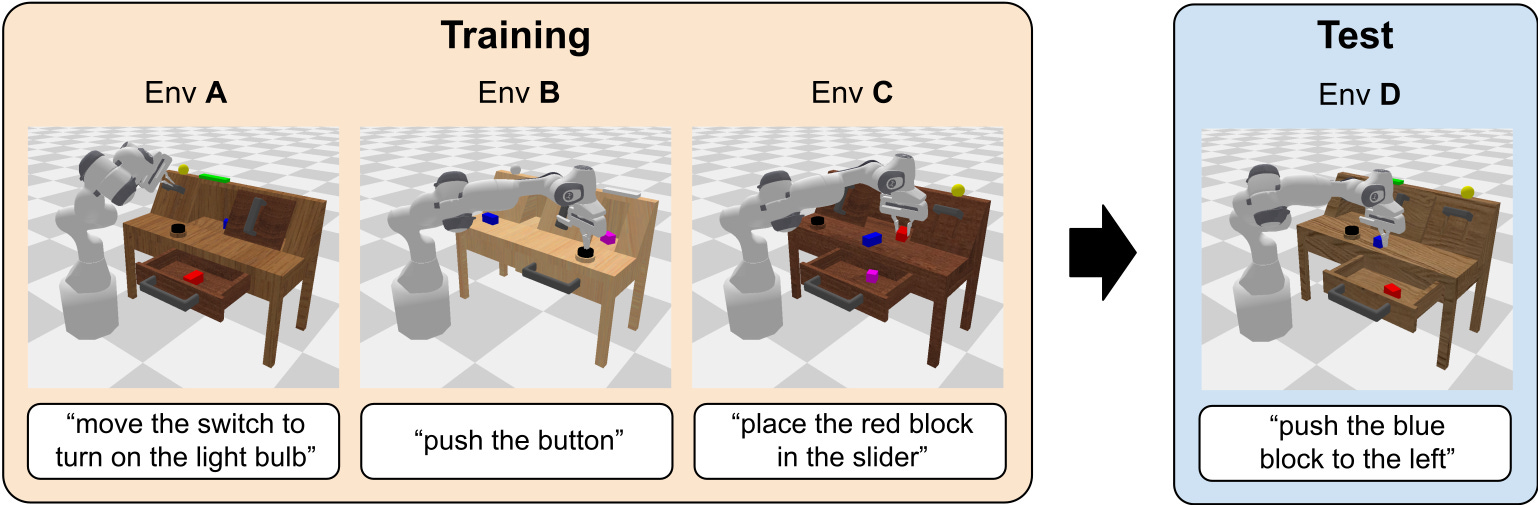
A commonly-used benchmark by Oier Mees for language-conditioned task execution. It uses the Franka Panda robot and has a simple setup with some light variation in objects and coloration, together with a good variety in pick and place tasks. Find it on Github here.
RoboEval
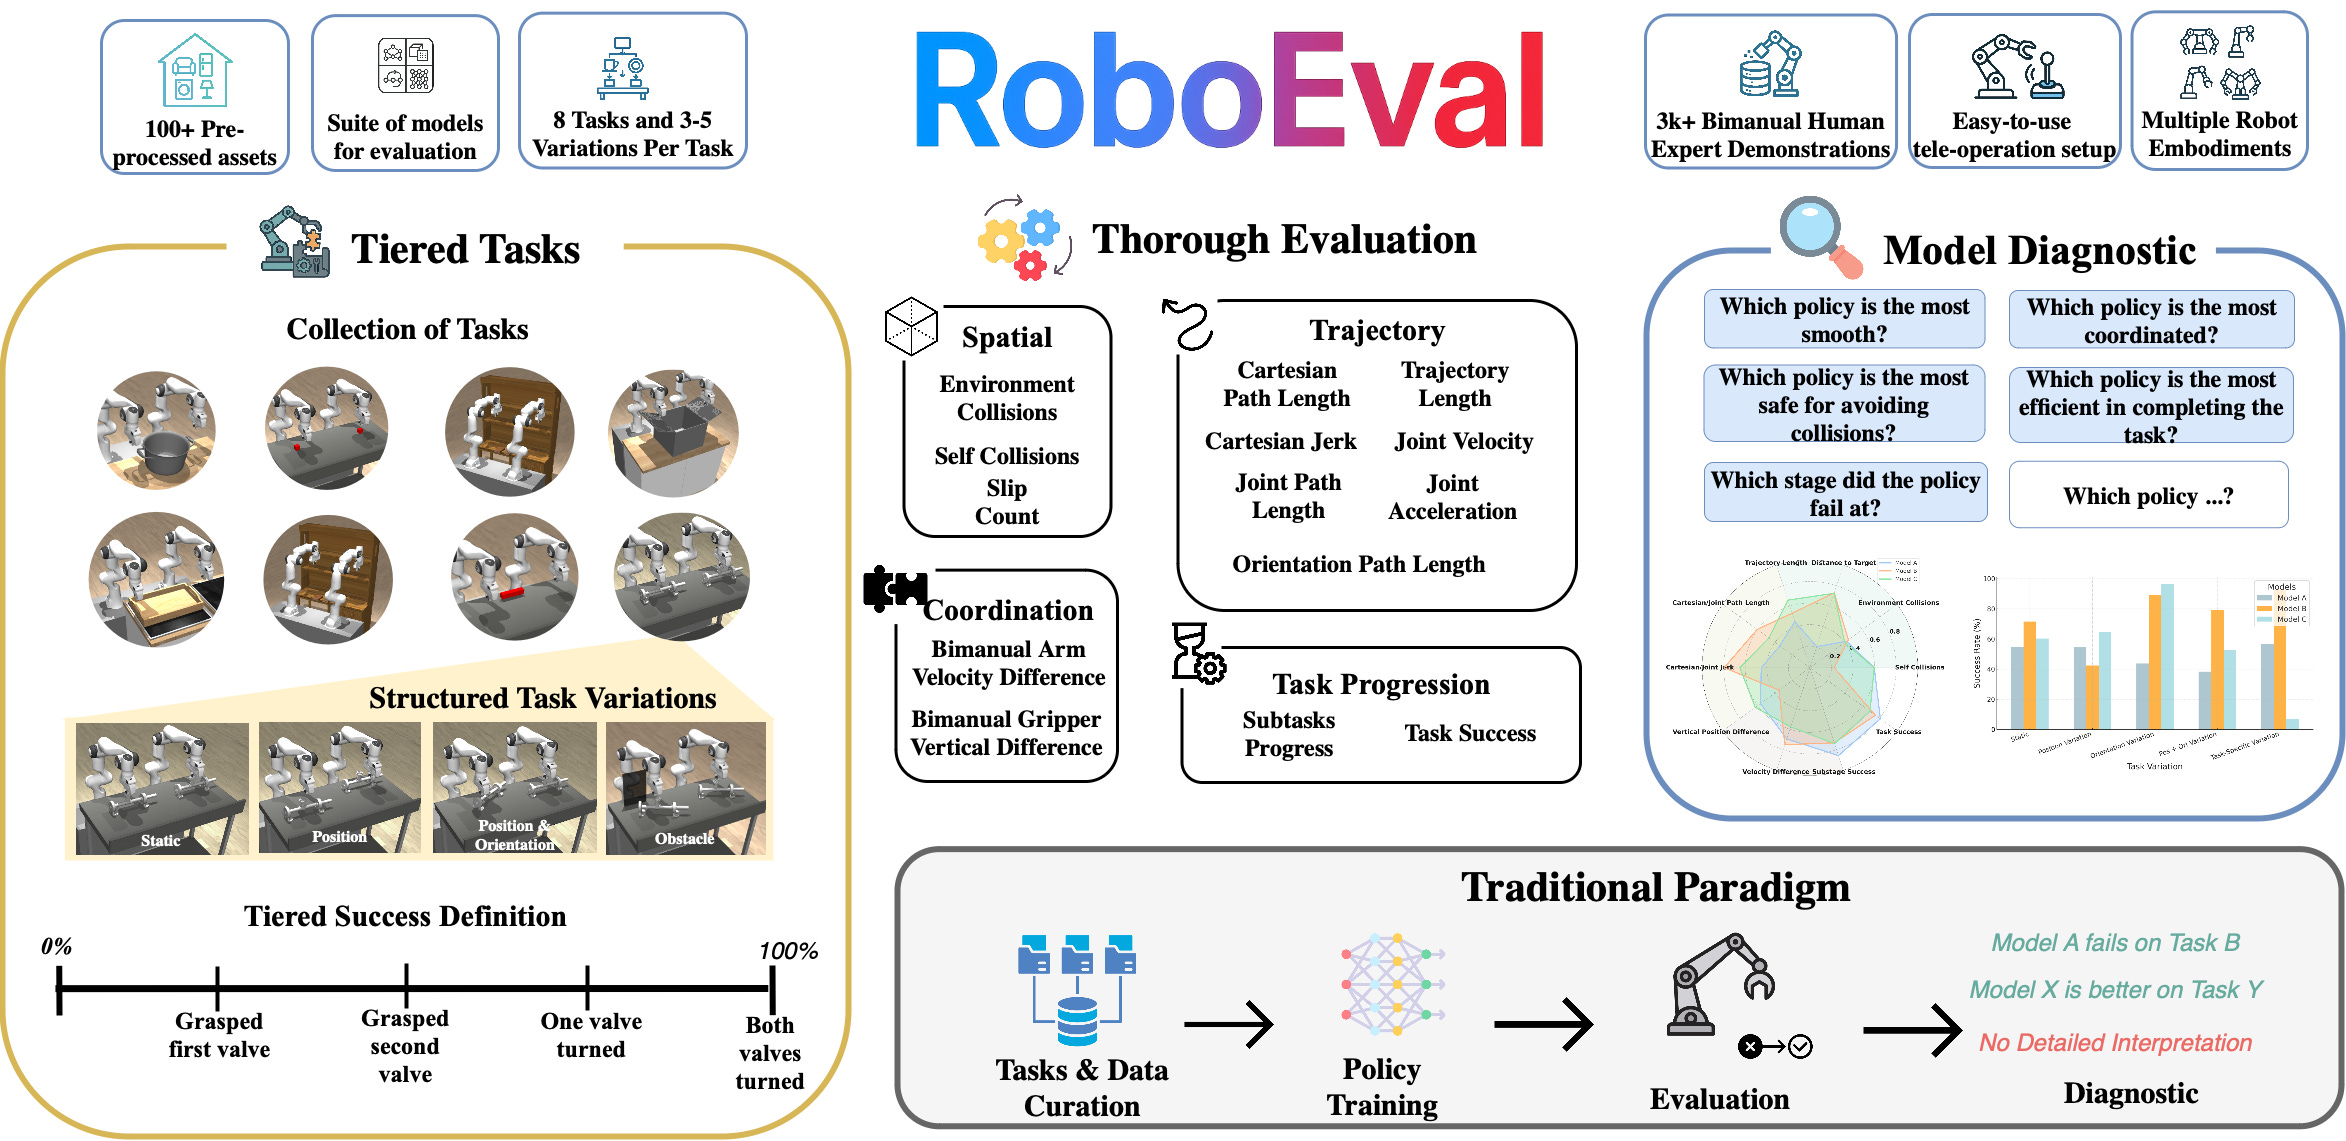
A benchmark of 10 base tasks and 3000+ demonstrations which aims, somewhat uniquely, to provide unique, non-binary metrics of performance, in order to give an idea of how and why experiments are failing: there are trajectory smoothness metrics, it tracks environment collisions, etc.
Check it out here. Thread with thoughts; original X thread.
RoboArena
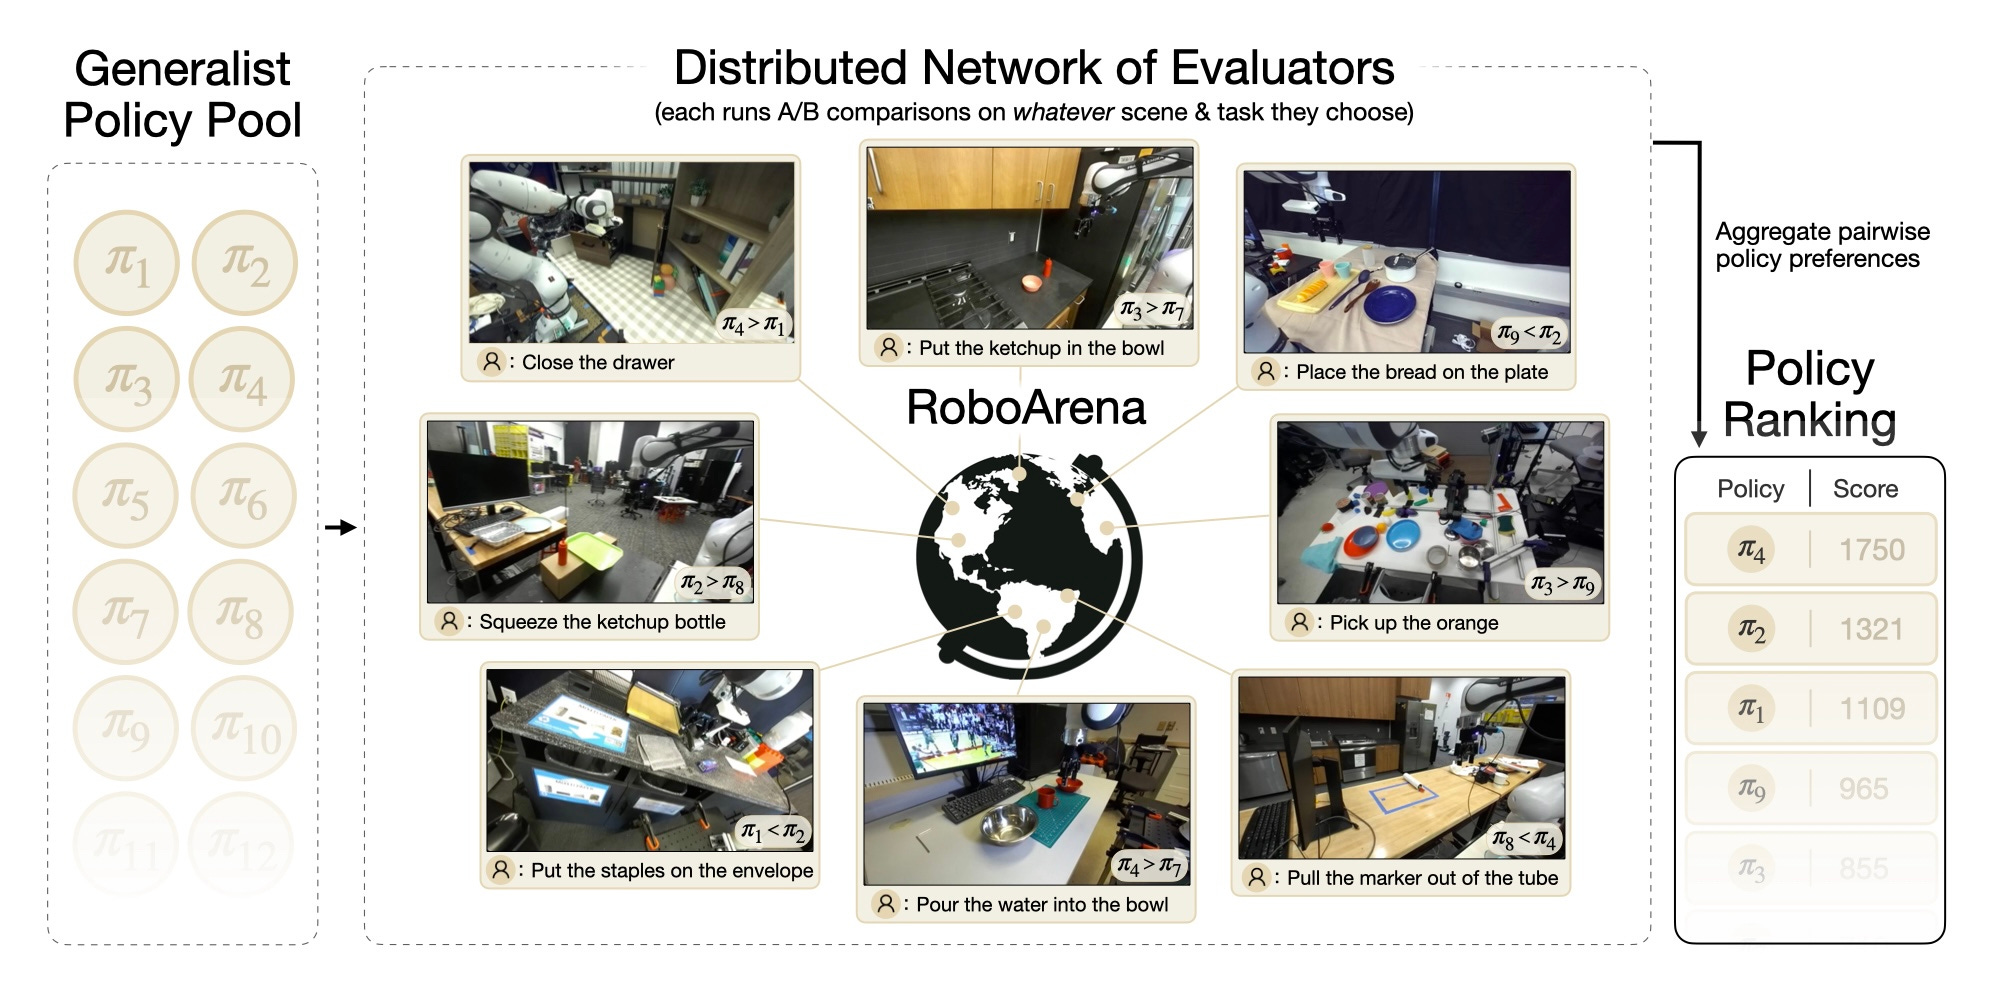
Real-world benchmarking via web socket to your policy. Grad students run evaluations in different university setups.
I’ve written about this one before, when writing about evaluations. I think it’s one of the best ideas for policy evaluation I’ve seen; though it’s still woefully limited in many ways.
See the X thread here, or check out the project site.
PolaRiS
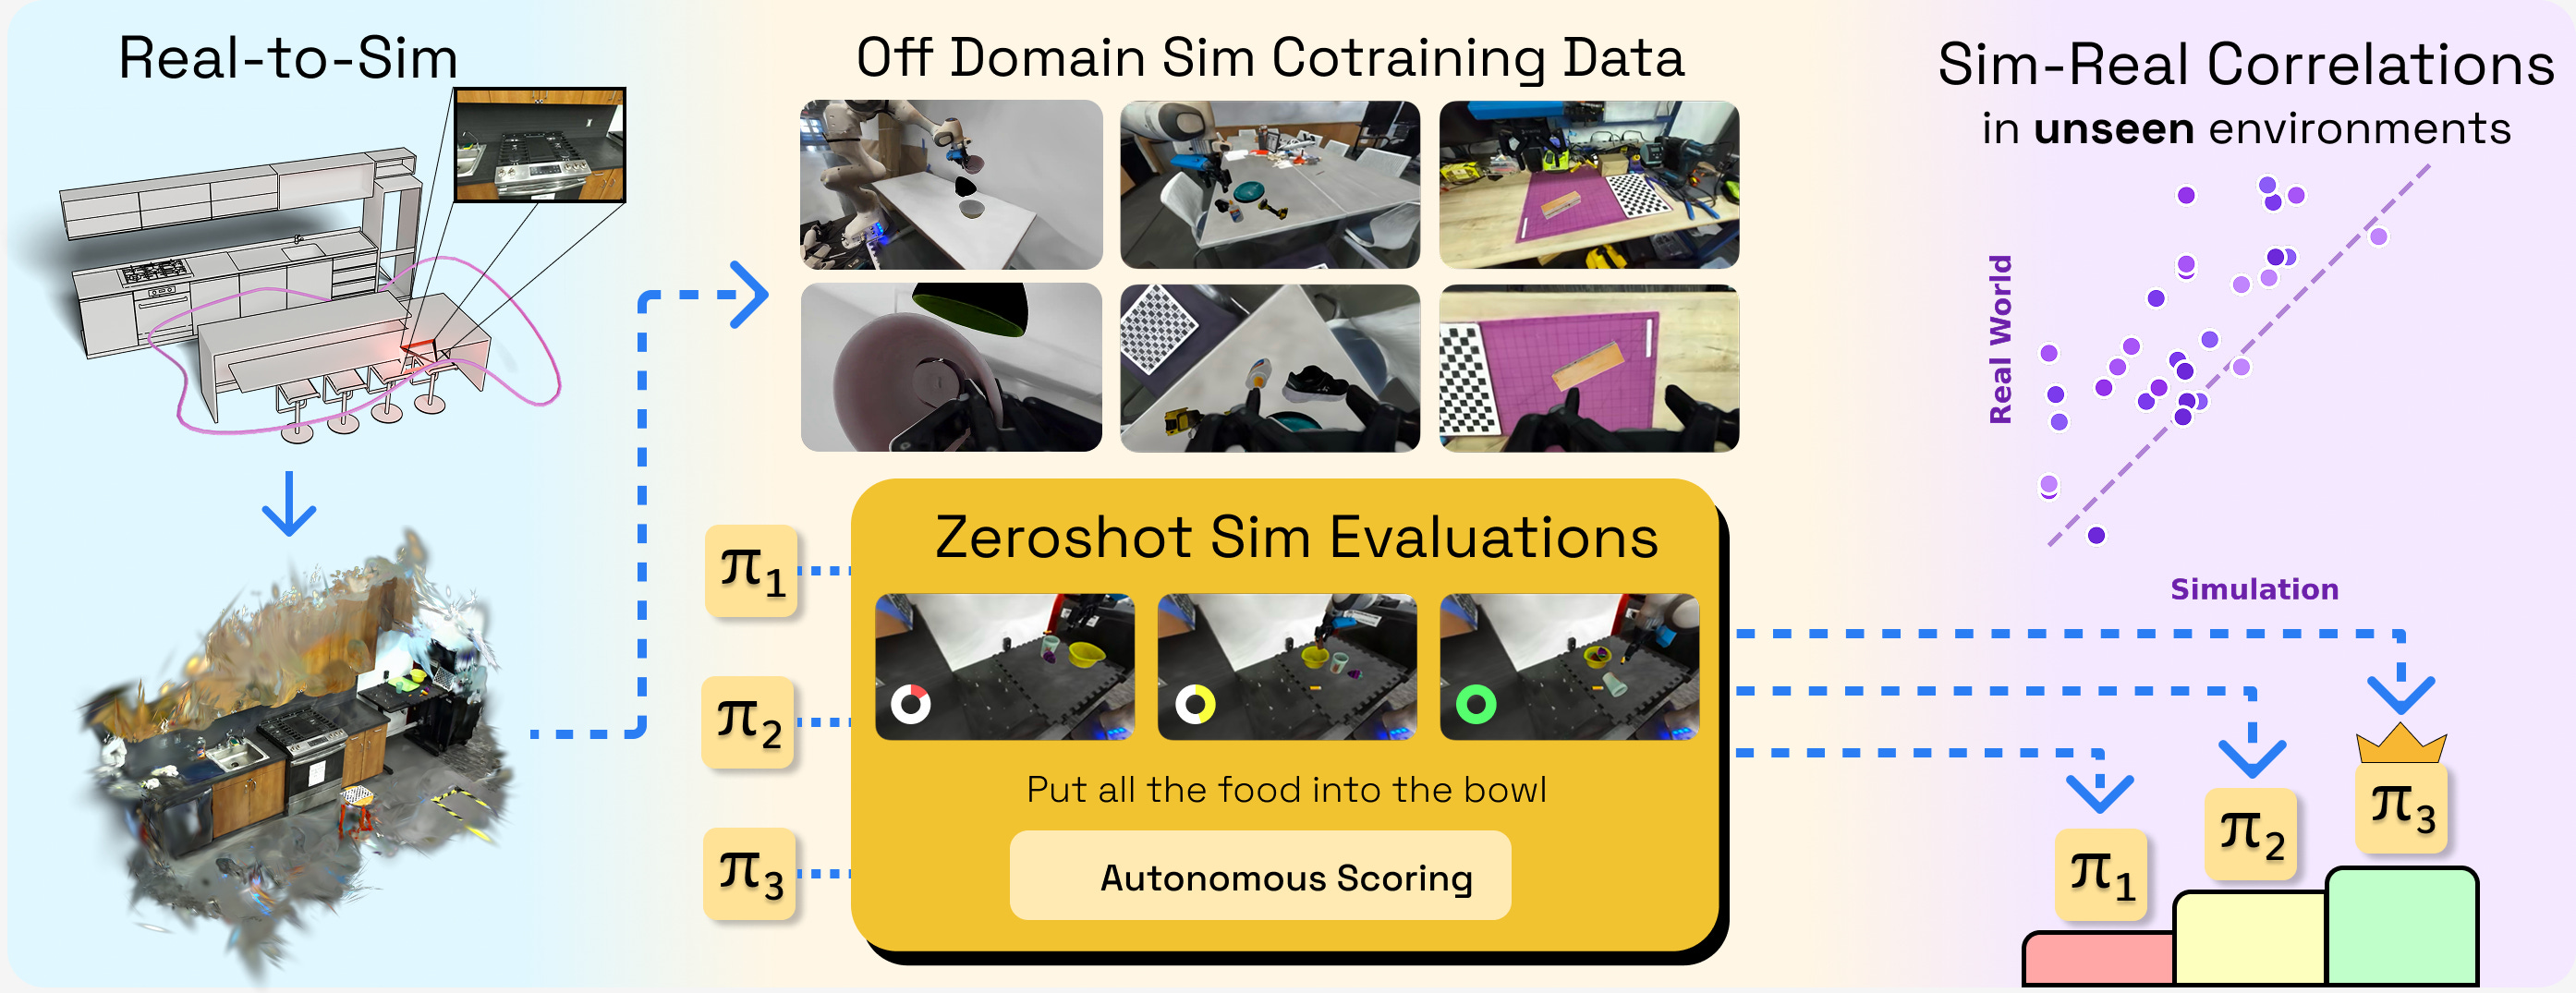
A benchmark specifically aimed at sim-to-real correlation. Scan an environment with your phone, use Gaussian splatting to construct a scene, and use a set of tools to create a photorealistic simulation. Ships with a set of “real-to-sim” environments in which performance correlation with the real world was validated.
Check it out here. Robopapers episode.
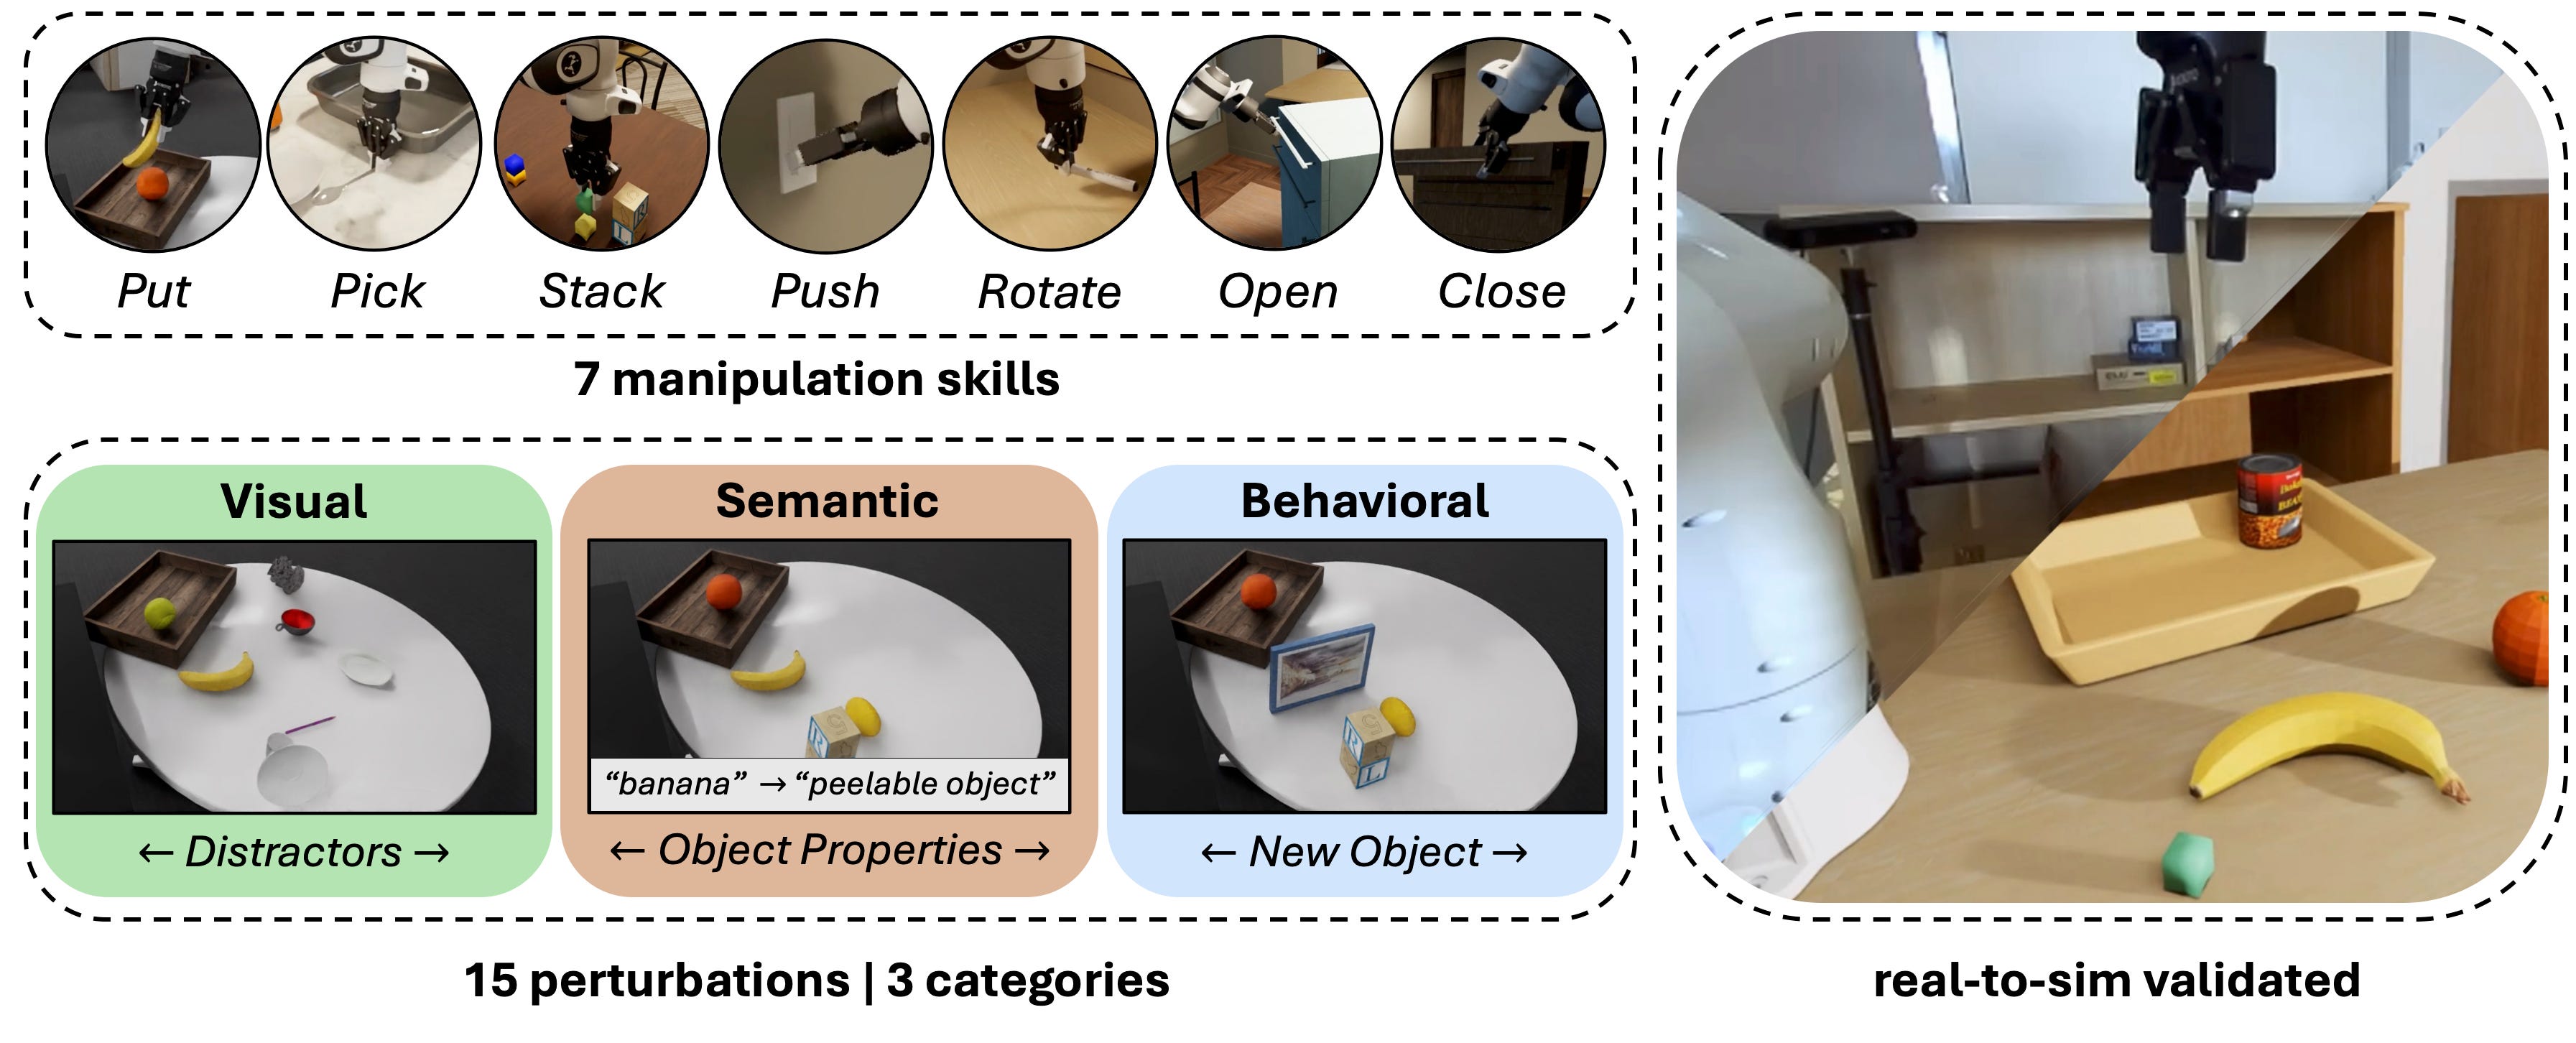
REALM: Real-to-Sim Validated Benchmark
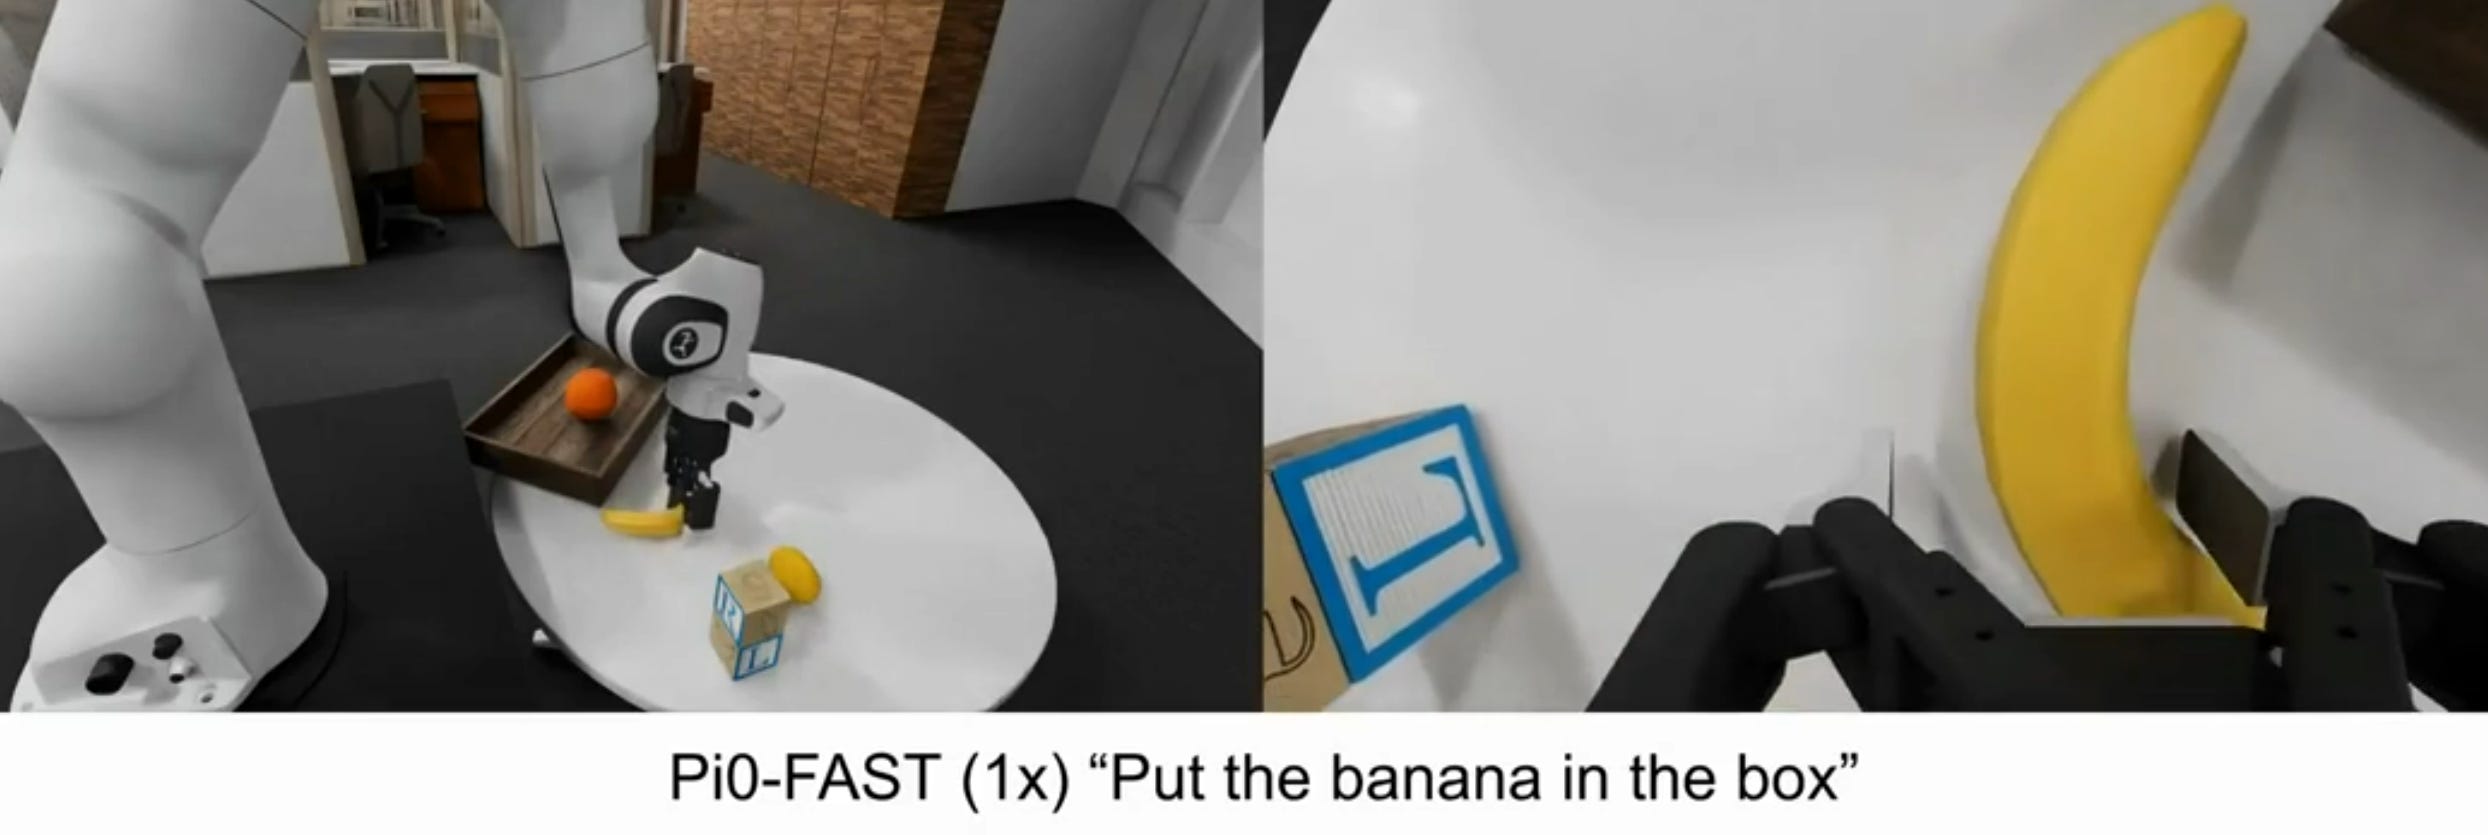
A benchmark specifically aiming to close the sim-to-real gap. Sedlacek et al. put together this benchmark designed to be a good simulation that closely represents the real world. See the post on this from Evangelos Kazakos on BlueSky.
Physics IQ
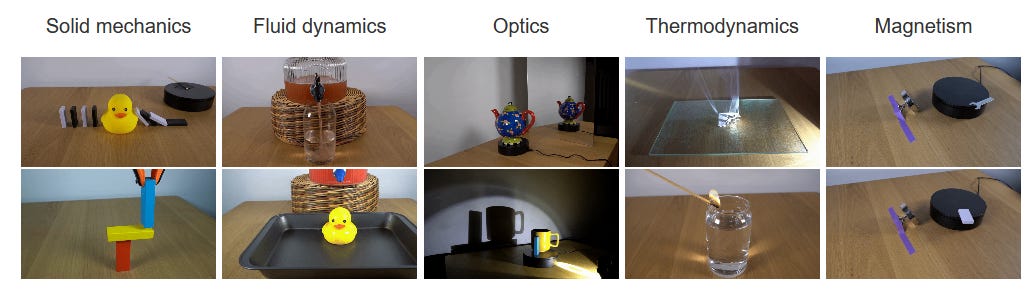
A video understanding benchmark - but of course video understanding is very closely related to robotics. Basically, how well can video models understand certain physical problems?
Check out the website and the thread on X. There was also an ICCV 25 challenge and associated workshop.
Conclusions
There are a lot of benchmarks and datasets out there; comparatively few (1) have gotten real uptake, and (2) show some actual correlation with real-world results. This is still an active area, and I personally am very excited about potential for real-world benchmarking like RoboArena (though it’s very expensive).
Ultimately the best benchmark is the real world — fortunately, with common platforms like the Unitree G1, we can expect people to open-source code that others can immediately use and deploy.
Learn More
How do We Quantify Progress in Robotics?

The release of the Imagenet dataset was a landmark moment for the nascent field of deep learning. This collection of what is now 14,197,122 images covering more than 100,000 concepts (“synonym sets” or synsets) was key in driving and assessing early progress in deep learning, in part because it signaled the ongoing shift from “better al…
Please also take a look at the MolmoSpaces benchmark:
https://molmospaces.allen.ai/leaderboard