

The best way to interact with your computer, clearly, is with human language. You tell it clearly what to do, and a modern coding agent can accomplish a great number of coding tasks. What’s the correct way to interact with a robot?
The problem is that language generally under-specifies any particular task. Language can tell you “put away the groceries,” but not the precise way you like all the labels arranged, or exactly where you put the milk, or the fact that you like all the jars pushed up against one side of the fridge in a particular way. Language is symbolic, but real-world, multi-modal data is generally lacking in meaningful symbols: we need to pick and choose and create them in order to transfer meaning via text across the internet. This, in large part, is the skill of a talented writer.
This leaves us a huge problem when trying to teach robots what to do. Robotics, as with most AI, works best when a problem statement is very clear, when there’s no room for interpretation, no ambiguity left for the model to guess at and potentially mess up.
We might imagine the perfect way of specifying a task, then, being a single demonstration of that task, on the same hardware, in a new context: it explains exactly how the robot should move and what it should do at each instant in an incredibly precise way (compared to text).
It’s also a way that is very intuitive for a human. We learn by watching and trying; we don’t learn manipulation by following sheets of written instructions. If you want to learn how to fix a dryer, you go to YouTube, not to Wikipedia. In short, if text and next-token-prediction was the foundation of GPT, it seems clear that video understanding is the equivalent for robotics and manipulation. Instead of prompting a robot with text, you must be able to prompt it with video.
And there have been a number of incredibly promising results this year which show how, finally, we can do just this: provide a video of a robot, and without re-training, execute a new task. Let’s take a look.
Research Proves the Way
Above: video from Behavior Prompting Policy, by Austin Patel et al.
Giving a single, intuitive demonstration in order to teach a robot is a powerful idea. One of our earliest episodes of RoboPapers covered Instant Policy, work by Vitalis Vosylius and Edward Johns which won the best paper award at the ICLR Robot Learning Workshop last year. The authors trained a specifically conditioned “foundation model” in simulation to make it possible to specify many different pick and place tasks at test time.
Such work was, however, a bit limited in what types of tasks could be performed, and this year we have seen more work which shows more scalable and general in-context learning. Prof. Edward Johns and his team had more great work featured on the RoboPapers podcast:

In their most recent work published in Science Robotics, the team taught a thousand tasks in a single day, using only a single demonstration per task. Another great read on this topic is the paper “Behavior Prompting Policy” (paper video above), which uses individual UMI trajectories as context to specify robot policies at test time. (UMI is Universal Manipulation Interface; an isomorphic data collection tool, or 1-to-1 copy of the robot gripper that a human can hold in their hands for fast and scalable data collection.)
These offer better specification for tasks and, importantly, allow robots to be “taught” given only a single demo trajectory. What this means, in the future, is that we can imagine the robot as a tool - one that someone who isn’t a robotics PhD or industry veteran can then use to solve their own problems. And that, to me, is the essence of a GPT moment. But for this capability to really work, it needs to scale.
Scaling Comes to Robot In-Context Learning
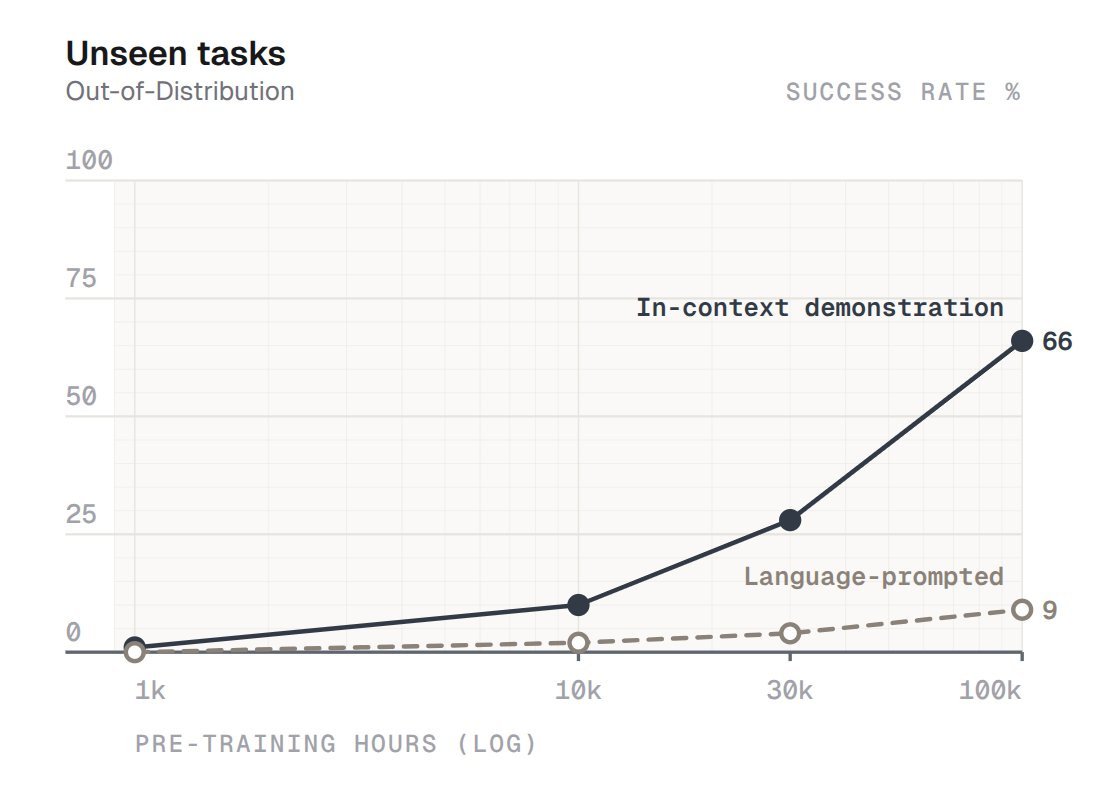
The most exciting robotics results of the year have come from scaling in-context learning for robotics, and these have not come from established players but from three well-funded and trendy Silicon Valley robotics startups, as well as from the phenomenal open research of Ant Group’s RobbyAnt robotics team. Generalist released GEN 1.5, a one-shot learner with results showing sim-to-real, robot-to-robot, and human-to-robot transfer. Rhoda showed human-to-video in context learning earlier in the year, based on their base model pretrained on years of egocentric and exocentric video data. And most recently, Skild went into great detail explaining their foundation model with incredibly exciting scaling results for in-context learning.
Taken together, these four results have demonstrated conclusively that it is possible to scale in-context robot learning for general manipulation tasks, and have provided some insights into what data is necessary and how to build such models.
The training recipe will look familiar in some ways; it’s a prompt, adding conditioning tokens to a transformer. But unlike in large language models, this is not a behavior that seems to arise naturally. Instead, you often need to specifically train robotics foundation models to include conditioning on previous video.
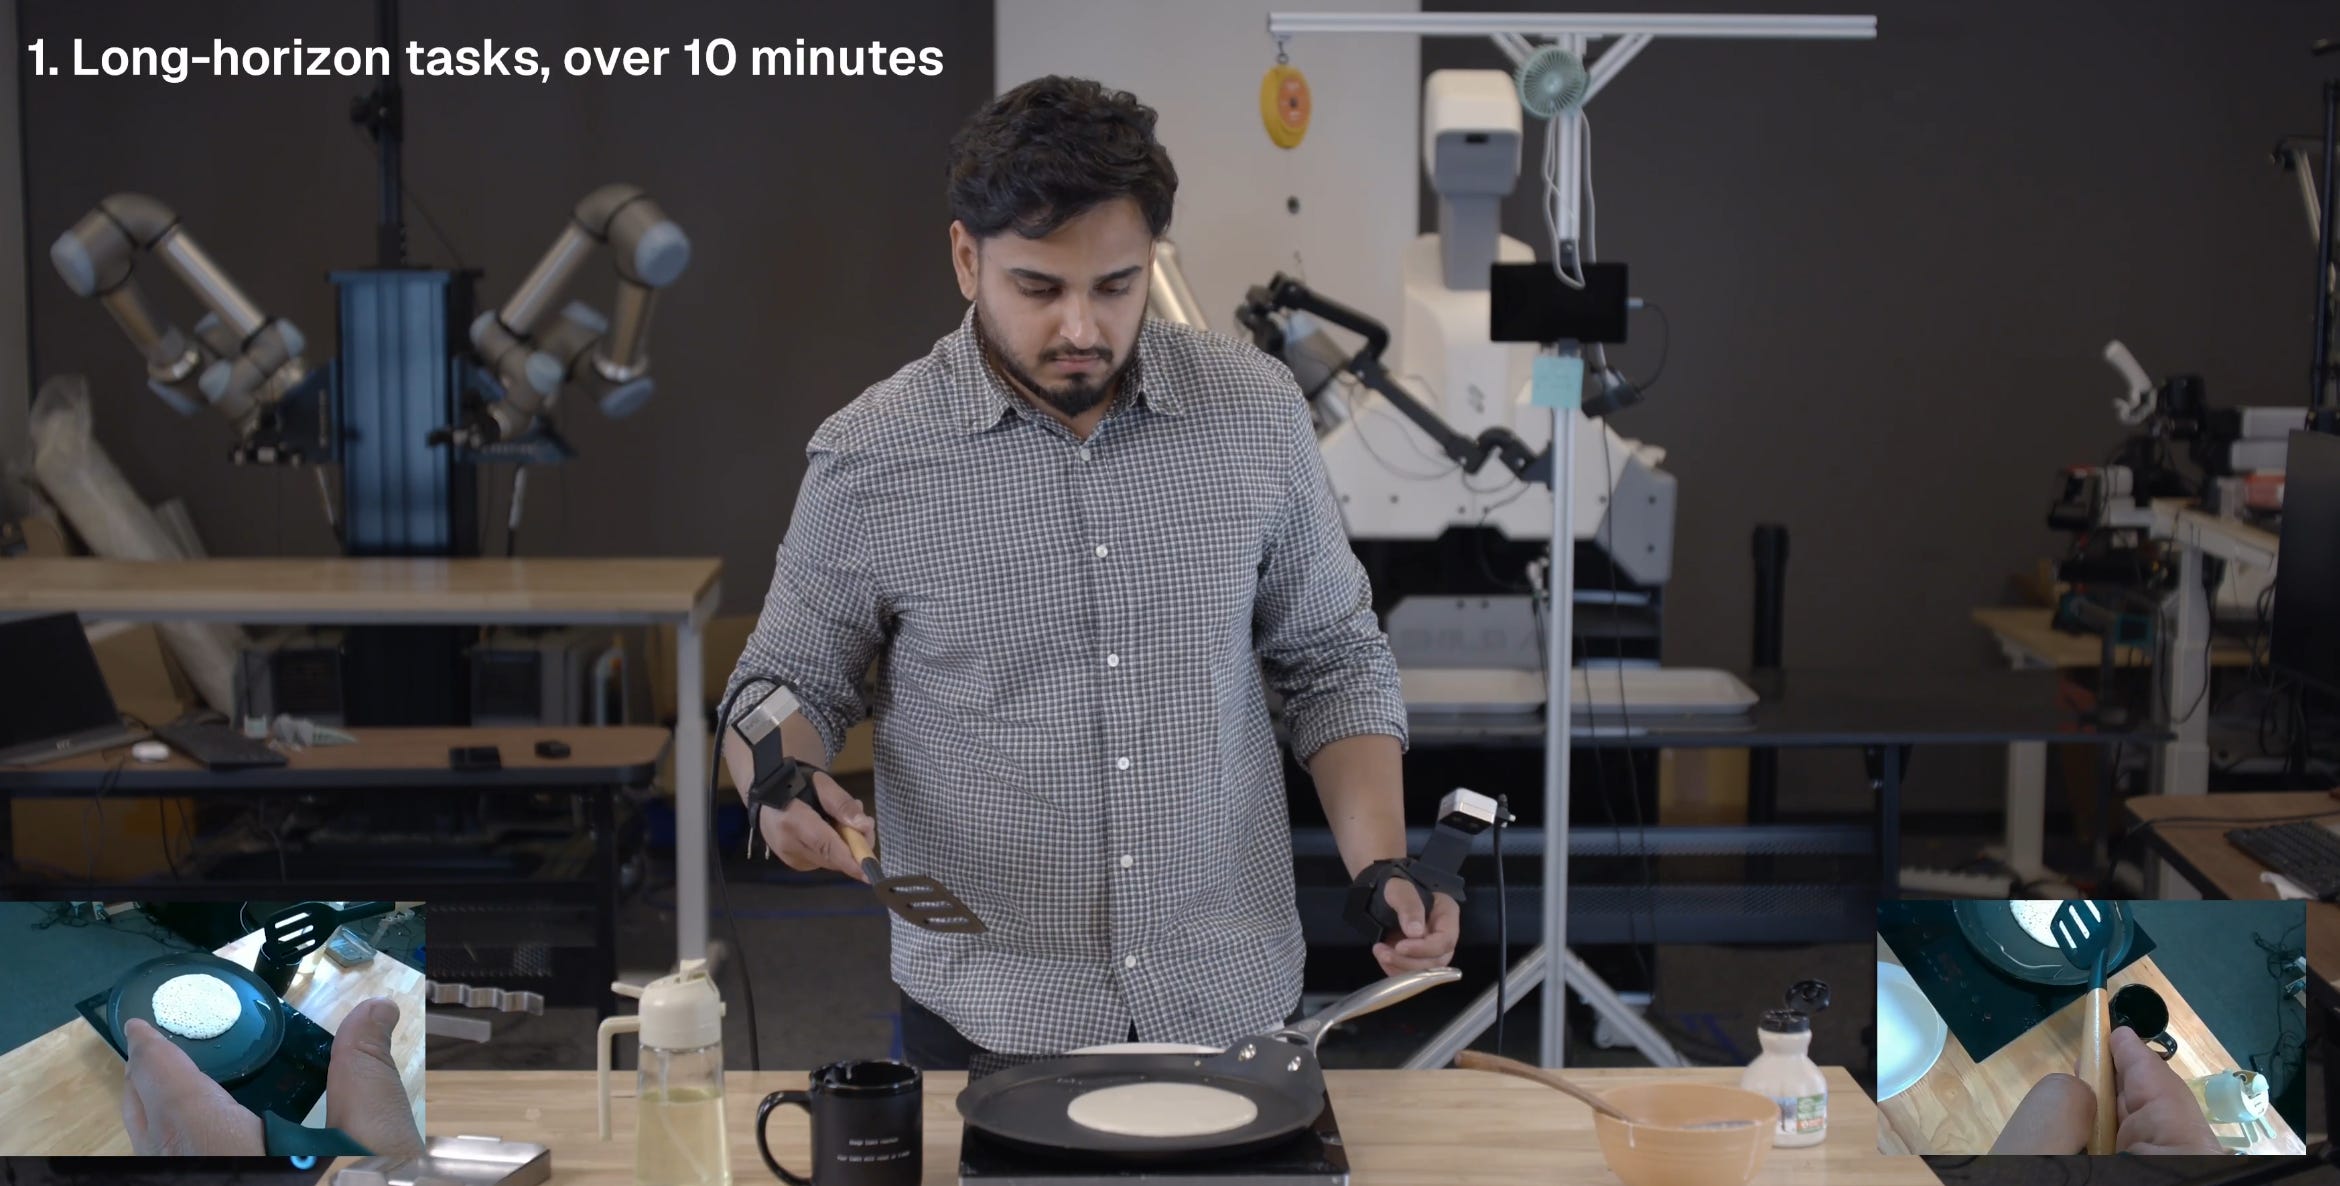
The Skild S1 version is interesting. It shares one commonality with the Generalist 1.5 model, which is that in neither case do they do data collection with purely human hands, instead using the end-effector cameras on the wrists. See the image above, a still from their release video.
But the big unique part that they push is completion of previously-unseen long horizon tasks. They show tasks like pancake flipping and plant potting which can take up to 10 minutes to execute. Particularly important is that it can do all this while moving beyond compositionality: meaning that it makes novel motions like pressing a coffee filter into a tunnel, or digging into soil in a particular way (GEN-1.5 and ACT-2 demonstrate compositionality).
Also, remember that part of why we care about in-context learning is that video is a better way of specifying tasks than language. With the Skild S1 blog post, we have some decent evidence showing this holds true at scale.
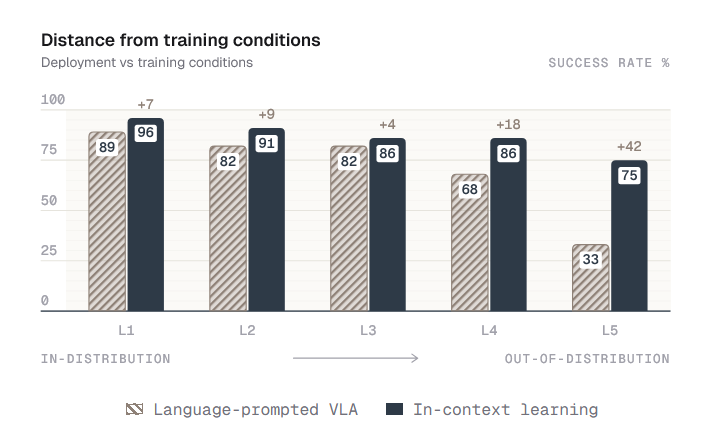
Another key result from their blog post: it took hundreds of post-training examples to reach the same level of performance. Post-training, in this case, means recording demonstrations of that particular task and fine-tuning the model — adjusting its weights — to improve success rate just on this task.
But post-training in this way is not without cost: it usually hurts generalization performance. And generalization performance, largely, is model performance: a robot needs to be able to handle the “long tail” of corner cases in order to be useful, meaning that any meaningful fine-tuning is likely going to hurt performance eventually unless it’s really, extremely comprehensive and the deployment domain is very well understood (or it’s just done in a closed loop with your final deployment, taking many extra months and thousands of data-hours).
So here we see a route out of this expensive, risky fine-tuning trap. Instead, just train bigger models on more data and prompt your way out! This is a much better solution in my mind, and will make robotics deployments far more scalable.
Training a Robot Foundation Model with ICL
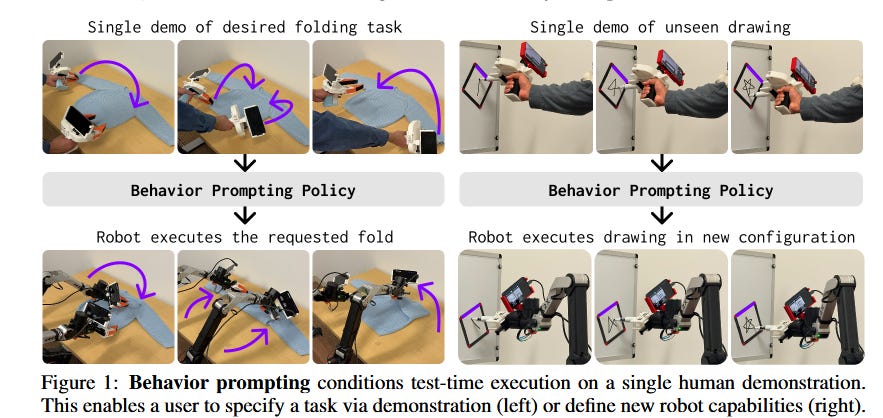
As mentioned above, for in-context learning on robots to work, we want to train models which take in long-context video and potentially proprioception information, and which specifically pair this long video input (from mixed embodiments) with robot execution trajectories. This makes it easy to, say, teach your home robot how to fold a particular new shirt, as shown in the Sunday Robotics ACT-2 blog post.
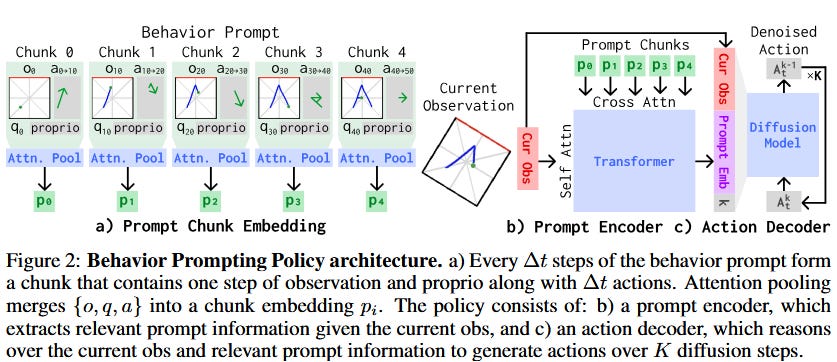
Mixed observation and proprioception information go into the robot model and form the “prompt,” which specifies how the robot will act. There’s a clear analogy here to how large language models work, but based on video and proprioception information instead of text.
One interesting note will be where the data comes from. Some of the coolest, most futuristic results — such as stacking from GEN 1.5 and bin sorting or drawing from Rhoda — show tasks being executed by a human, with no special tools or gear to make the human more robot-like (as per Skild S1). This doesn’t seem to work very reliably yet, but when it does it shows a real vision of a robot that, say, your parents could use: one where you unpack it and show it something, and it “just works.”
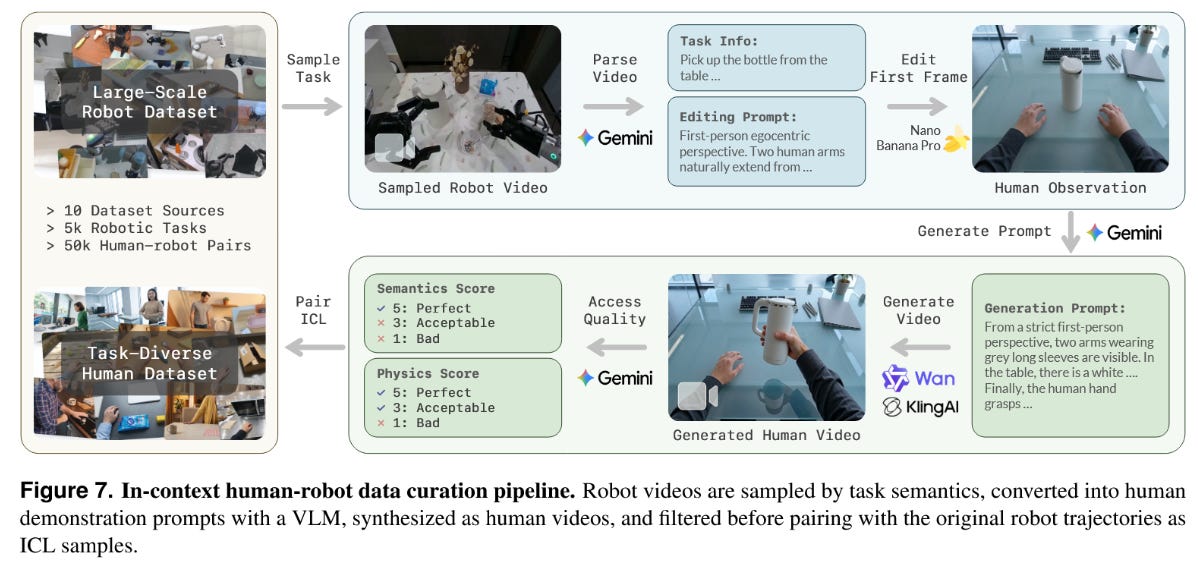
The Lingbot VA-2 paper shows how this can be implemented. They took real robot trajectories and synthetically generated paired human video out of these trajectories, which they can then use for in-context learning on a variety of pick-and-place tasks.
On GPT Moments
The term “a GPT moment for X” is somewhat overused. To me, personally, the mark of general intelligence is when we can build tools — robots — that users will be able to deploy, which will do things that surprise the tools’ creators with their generality and capability when put in the hands of other people. In the world of LLMs, this is most evidenced by the recent trend of AI models solving open problems in frontier mathematics.
The reason that, to me, these long-context video results feel like a hint at a true GPT moment, then, is that robotics can now become a true general-purpose tool. With in-context learning on video or a single demo, I can finally imagine unboxing a robot, taking it into a new place of business, and showing it some task to get it to run within a single day. Are we there yet? No. But the road seems clear.
Final Thoughts
There are still open questions as to how best to implement in-context learning for robots. Generalist GEN 1.5, for example, does test-time training — they can improve results by taking a few gradient steps. This might be a good tool in your toolbox, if you want to improve performance. More research and development will help figure out which tools are best across a very wide range of tasks.
Eventually, this becomes a human interface problem: what tools will make robot users most successful? Which will help humans best envision the tradeoffs between policy specification choices and enable large-scale robot deployment?
One final caveat: in many of these results, the in-context learning success rates are still nowhere near production level, and many of the results are constrained to task components that have been seen before, even if zero-shot tasks are possible. And we do see signs of long-horizon unseen tasks from Skild S1. Still, the robot isn’t yet going to learn some wholly new skill, at high success rates, without more data or on-robot reinforcement learning.
All in all, I think this has been an incredibly exciting year for robotics, and it feels more obvious than ever that this technology will have a massive impact in the coming years.
If you like this, please subscribe and share the post, and leave a comment with your thoughts below.
I was looking for a survey of a similar topic, thanks! Are there any approaches where some RL is used in the loop to robustify the new task performance?